The free allowance
Your first 3 merged deliveries are free. No card, no subscription. A slot is taken when you label an Issueai-ready, and it is refunded if that delivery does not end in a merge — an Issue that ends ai-blocked, or that you close without merging, gives its slot back. That is why the allowance is described as three merged deliveries rather than three attempts.
Counting is per Issue and idempotent: re-labelling the same Issue does not consume another slot. Re-delivering the same Issue after a refund uses the slot it gave back.
When the allowance runs out
The next Issue you labelai-ready has that label removed and gets a comment saying the free allowance is used up, with a link to subscribe.
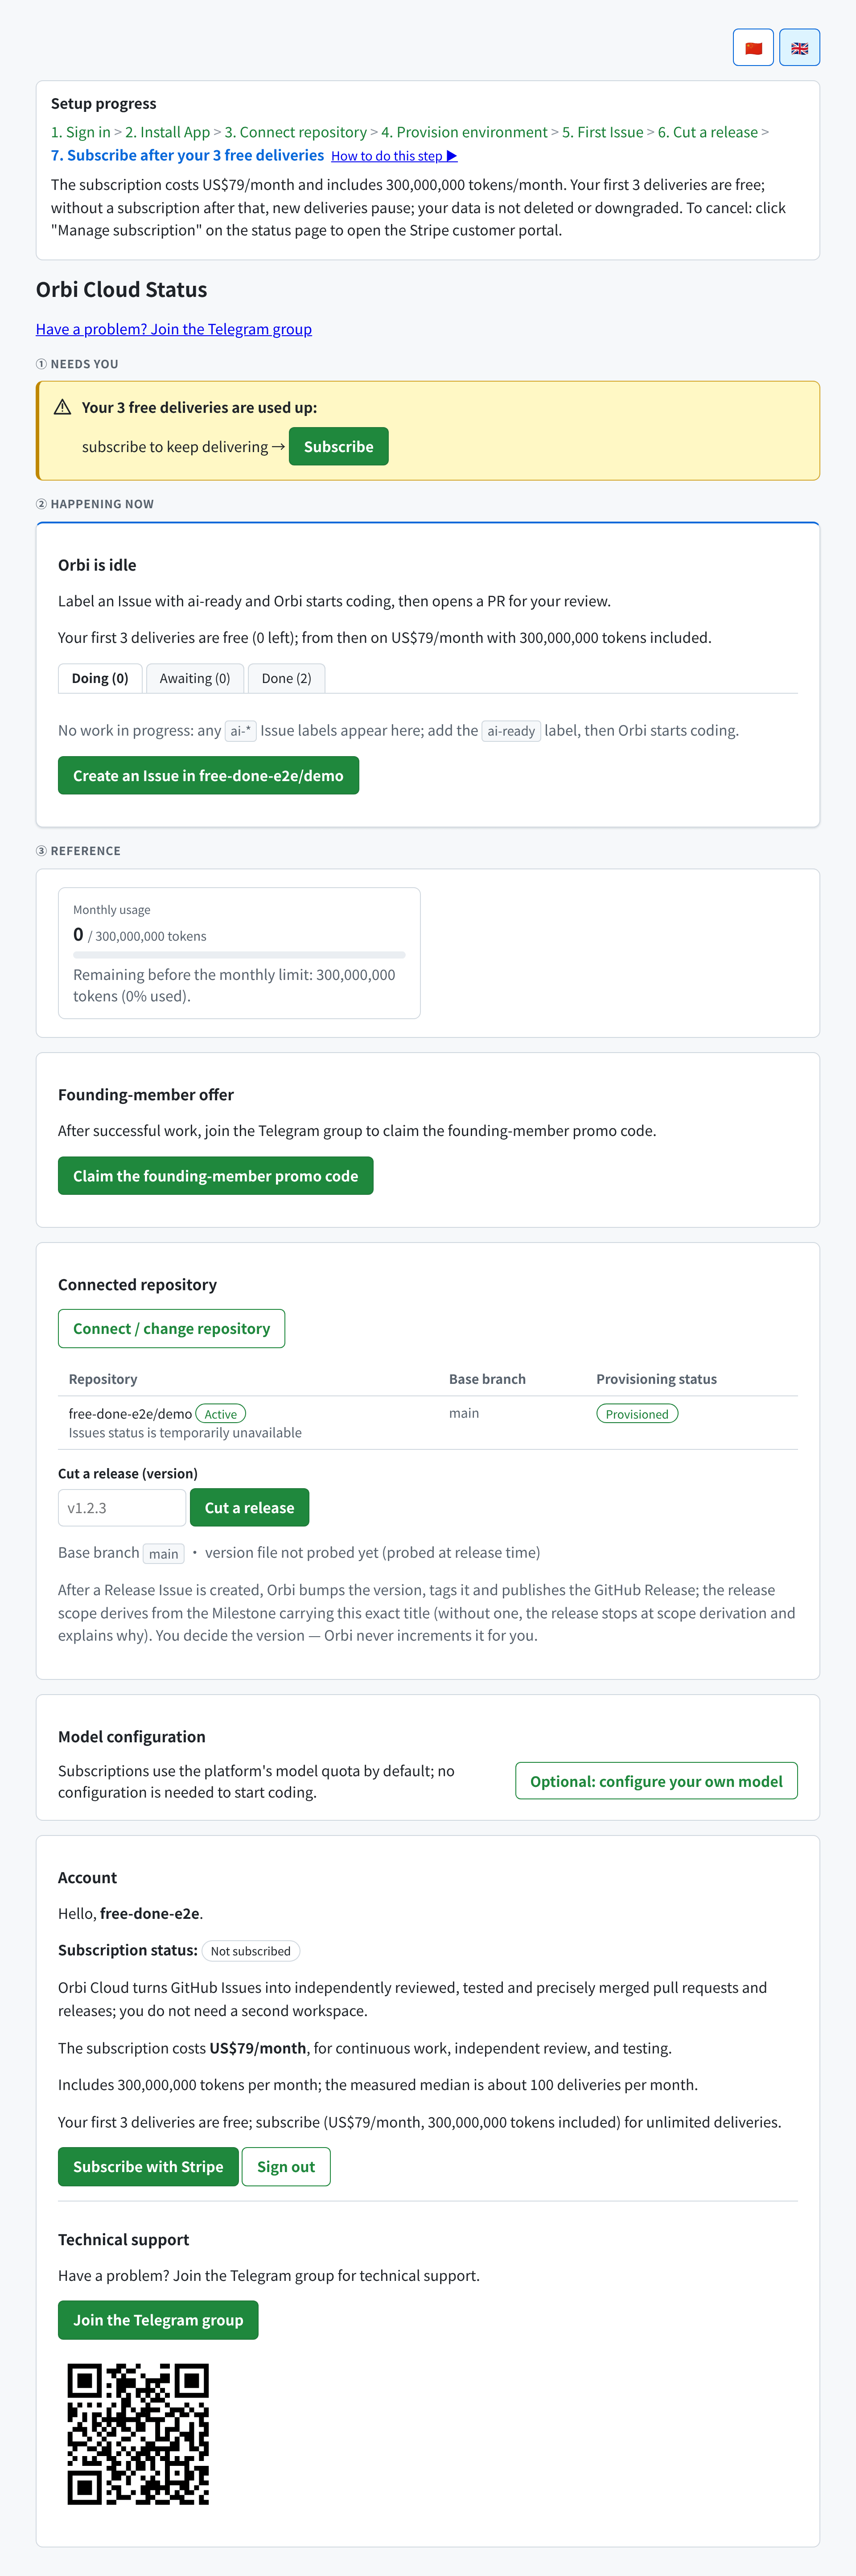
The status page for a tenant whose free allowance is used up
ai-ready label to the Issue. The label is not restored automatically. Deliveries already in flight when the allowance ran out finish normally.
The monthly token quota
A subscription includes 300,000,000 tokens per calendar month (UTC). There is no per-token overage billing — when the allowance is used up, new deliveries pause until the next month starts. Usage counts input tokens, output tokens and cache-read tokens. Re-delivering the same Issue accumulates: each delivery is a separate run. As a rough guide, 300M tokens covers somewhere between 85 and 400 merged deliveries depending on how large the tasks are. That range assumes your provider supports prompt caching.Watching your usage
The Monthly usage card on the status page shows tokens used against the limit, how many remain, and a percentage bar. Beside it, Monthly cache hit rate matters more than it looks. Cache-miss tokens cost roughly 50 times more than cache hits, so a rate below 90% burns the quota noticeably faster. If yours is low, it is worth understanding why before assuming the quota is too small. Each work item also has its own usage detail — input, output and cache tokens, runtime, model requests and how many times the run resumed. Work that never reported usage shows—.
When the quota runs out
The behaviour matches the free allowance: theai-ready label is removed from newly dispatched Issues and a comment explains why, naming your actual usage and the cap. In-flight deliveries are untouched.
To resume: wait for the next calendar month, or configure your own model key — BYOK usage is measured but never paused. Either way you must re-apply ai-ready yourself.
If Orbi’s usage measurement is unhealthy, the quota check fails closed rather than guessing — new dispatch pauses with a comment saying usage collection is temporarily abnormal. This is deliberate: it will not spend against a number it cannot trust. It clears on its own.
What is never interrupted
Neither limit ever stops work in progress. Both guards only act on an Issue that has just been labelledai-ready and carries no other ai-* label — so a delivery that is ai-in-progress, ai-pr-opened or ai-fix-needed runs to completion regardless.
Platform upgrades and deployments have the same property: they never restart a delivery that is already executing.